HPC in the AI Agent Era

QUT · SCHOOL OF INFORMATION SYSTEMS · HDR WORKSHOP

HPC in the
AI Agent Era

From HPC Fundamentals to Research
Workflows with AI Agents

Dr Zhipeng (Zippo) He

School of Mechanical, Medical and
Process Engineering

Queensland University of Technology
Research workspace with AI assistance and shared HPC resources An illustrative cycle: AI assistance helps prepare a job in the researcher’s project; the job travels to HPC resources; results return for inspection with AI assistance. The researcher directs the task. This is a conceptual overview, not a recorded execution. HPC resources Run experiments · analyse data Your research project code / data / job script AI agent assistance Read code · prepare the job Read logs · explain the results HPC expands what you can run. AI agents help you put it to work.
P01 / 46

Acknowledgement of Traditional Owners

QUT acknowledges the Turrbal and Yugara, as the First Nations owners of the lands where QUT now stands. We pay respect to their Elders, lores, customs and creation spirits. We recognise that these lands have always been places of teaching, research and learning.  QUT acknowledges the important role Aboriginal and Torres Strait Islander people play within the QUT community.
BEFORE WE BEGIN / WHAT TO EXPECT

What to expect from this workshop
Understand the choices. Apply them to your research.

Together, we will

  • Recognise where HPC can help.Connect research needs to useful computing capabilities.
  • Follow a research workflow on Aqua.Understand requests, execution, resources and results.
  • Work with an agent deliberately.Give context, set boundaries and check its work.

We will not walk through

  • Getting your HPC access set up.Account applications, access approval and first login.
  • Every task, command by command.The examples explain choices, not every possible procedure.
  • Setting up each person’s research project.Software installation and project-specific troubleshooting.

Bring a task. Question the choices. Identify your next step.

Use the demonstrations and discussion to relate the workflow to your own research.
Follow the linked tutorials afterwards for step-by-step instructions.

P03 / 46

Think of one task from your research

BRING YOUR RESEARCH INTO THE ROOM

Think of one task
from your research.

What are you trying to find out,

and what does your computer need to do?

Keep that task in mind as we meet five researchers.
P04 / 46

Sam has three weeks to complete 30+ experiments and revise the paper

01 / WHY HPC?

Sam has three weeks to finish
30+ experiments and revise the paper.

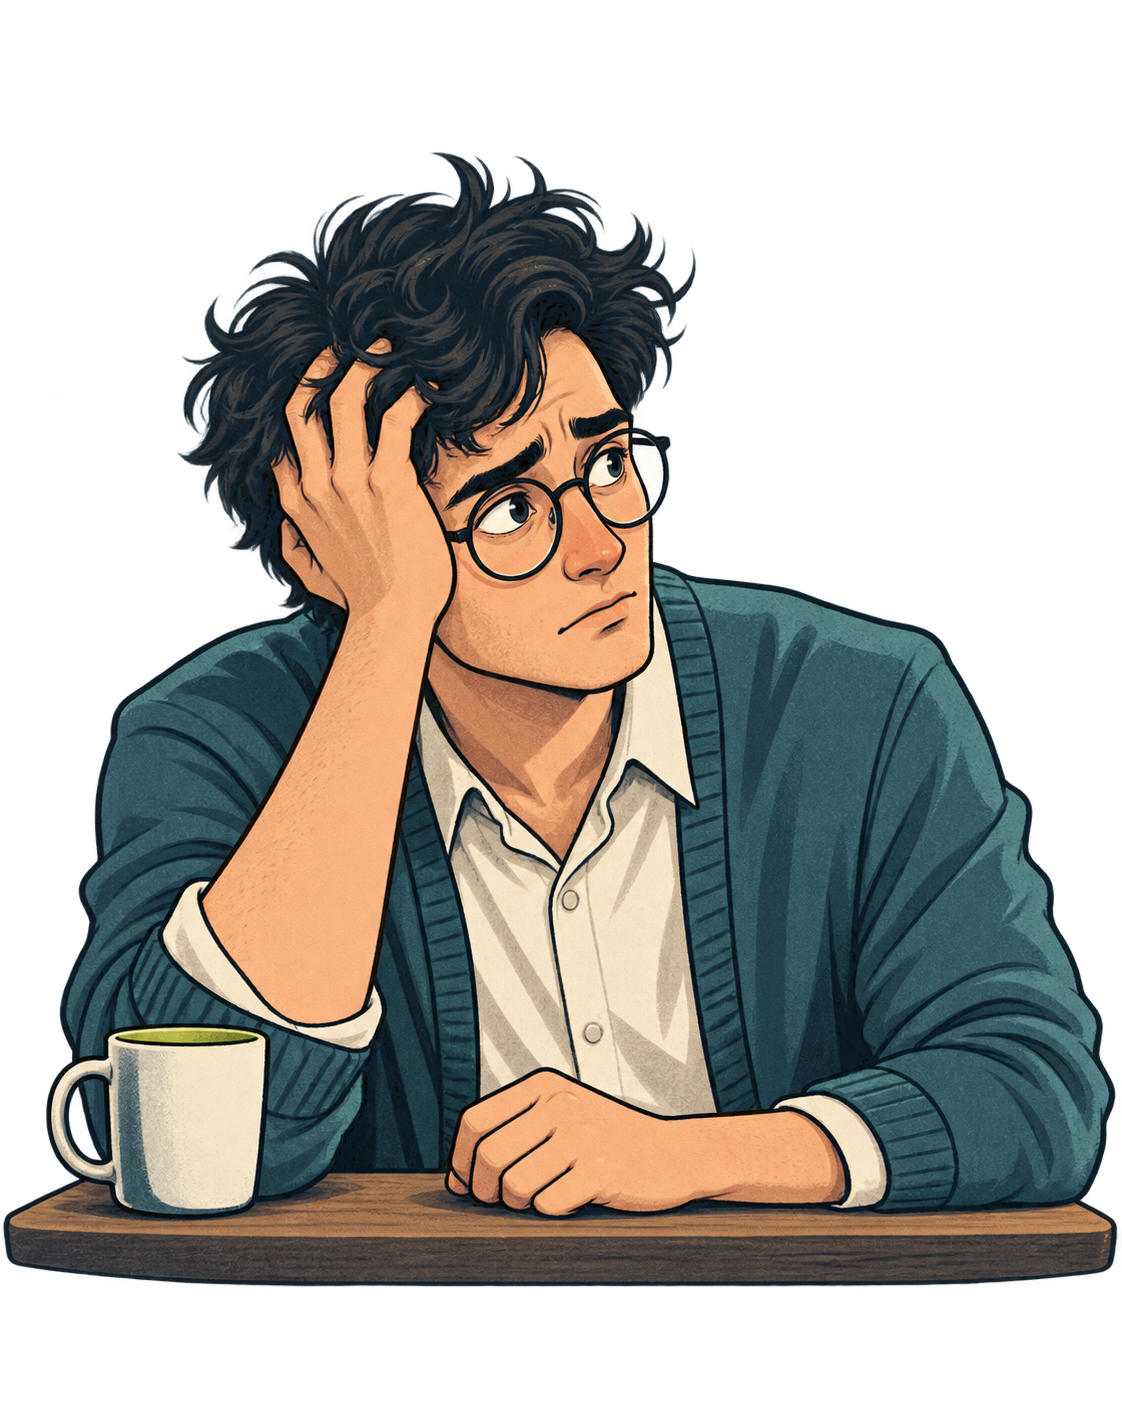
Meet Sam.A PhD researcher facing a paper revision.
Illustrated Sam, a tired researcher holding his head and looking at the waiting experiments.

“And I still have to
write the revision…”

REVIEWER 2

“Add baselines, ablations and repeated runs.”

35runs waiting
One workstation GPU
Results
RUNNING
REPEAT 1Baseline A
0completed
3 weeksuntil the revision deadline

The experiments run one at a time.
Interpretation and writing still need time.
P05 / 46

Alex’s analysis keeps running out of memory

01 / WHY HPC?

Alex’s analysis keeps stopping.
There isn’t enough memory.

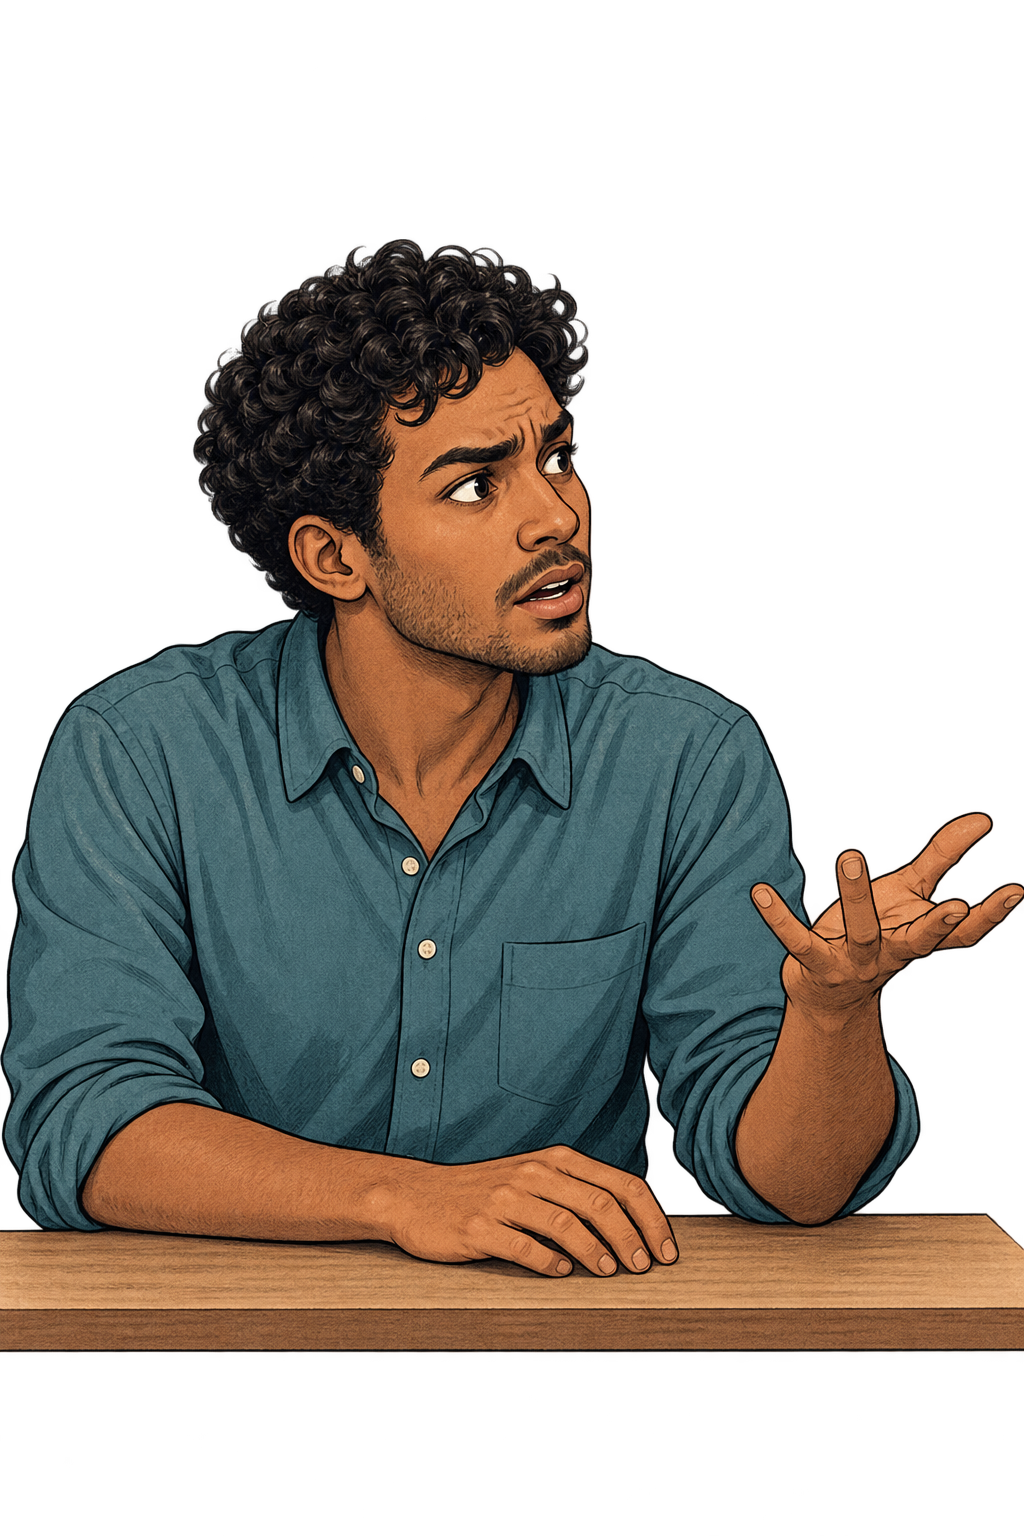
Meet Alex.A researcher working with a large analysis.
Illustrated Alex looking at the failed analysis in frustrated disbelief.

“It fits on disk.
Why won’t it run?”

Alex’s workstation
Starting the analysis

The program needs working memory.

1Read inputs
2Build model
3Compute next step
RAMWorking memory available to the analysis
Loaded data
Model state
Available
Installed RAM ends here
Required memoryWorking arrays keep growing beyond this machine’s capacity
The dataset stays
saved on disk.

Reading a file is only the beginning.
P06 / 46

Priya needs separate machines for the experiment

01 / WHY HPC?

Priya’s experiment needs
more than one machine.

Meet Priya.A researcher studying distributed systems.
Illustrated Priya, a fictional researcher facing this computing problem.

“I can test the code.
But not the real setup.”

What changes when components run on different machines?

WHAT PRIYA HAS
One laptopABCAll three share its CPU and RAM

Local processes can test the code.

NEEDED FOR THE EXPERIMENT

Messages cross a network.
Each machine has its own CPU and RAM.
Required setup unavailableOne laptop cannot supply these separate machines.
P07 / 46

Lily needs her everyday laptop while preprocessing continues

01 / WHY HPC?

Lily needs her laptop back.
The computation is still running.

Meet Lily.A researcher preprocessing a large dataset.
Illustrated Lily, a fictional researcher facing this computing problem.

“My workday cannot
wait for this to finish.”
Day 1Day 2Day 3…
Lily’s everyday laptop
DATA PREPROCESSINGStill running
Read Transform Save Repeat
WRITINGThesis draft
Needs this laptop
MEETING
Supervisor catch-upNeeds this laptop
TEACHINGTutoring session
x + y = ?
Needs this laptop
The working day moves on.The computation still needs the same device.
P08 / 46

Maya changes her data while her teammates keep older copies

01 / WHY HPC?

Maya updates her dataset.
Her teammates still have the old copy.

Meet Maya.Maya, Leo and Chen work with the same large dataset.
Illustrated Maya, a fictional researcher comparing copies of the data.

“I changed my copy.
Did you get the update?”

✓ Same code in GitSeparate data copies · sample rows shown
Removing duplicates…

Maya

Large dataset
012
024
024
038
061
061
075
089
v1Local copy

Leo

Large dataset
012
024
024
038
061
061
075
089
v1Local copy

Chen

Large dataset
012
024
024
038
061
061
075
089
v1Local copy
Maya’s data changed. The other copies didn’t.
P09 / 46

What kind of system could help all five researchers?

01 / WHY HPC?

What kind of system could
help all five researchers?

“I need to run
more experiments
at once.
Sam
Sam
“I need
enough memory
for my analysis.”
Alex
Alex
“I need
separate machines
that communicate.”
Priya
Priya
“Keep it running
while I use
my laptop.
Lily
Lily
“We need to work
with the same
large dataset.
Maya
Maya
High-Performance ComputingHPC

Shared compute, memory and storage for research.

P10 / 46

Inside QUT Aqua

02 / UNDERSTAND THE WORK

Inside QUT Aqua.
Connected machines. Distinct roles.

QUT Aqua topology: login nodes, PBS Pro, compute resources and shared filesystems A laptop connects by SSH to Aqua login nodes aquarius01 or aquarius02. PBS Pro schedules work on CPU nodes, H100 or A100 GPU nodes, or the single large-memory node with 6 TB RAM. Compute nodes have their own CPU and RAM and communicate over InfiniBand. Login and compute nodes access Lustre home and work storage and Weka scratch storage. Coloured paths distinguish logical traffic, not separate physical networks. Icons represent resource groups, not node counts. QUT AQUA Compute nodes Each node has its own CPU and RAM Submit jobs Read / write InfiniBand HDR / NDR · node-to-node messages Your laptop Access & control New to Aqua? Complete the HPC AccountRequest form. SSH Login nodes aquarius01 / aquarius02 Prepare · submit · monitor PBS Pro scheduler Queue · allocate · launch CPU nodesCPURAMAMD EPYC · 1.5 TBGPU nodesCPURAMGPUH100 / A100Large memoryCPURAM1 node · 6 TB RAM Shared filesystems Lustre: /home · /work Weka: /scratch Aqua resource groups · logical paths, not physical wiring Job controlFile I/OMessages
P11 / 46
02 / UNDERSTAND THE WORK

What happens when you
request compute?

Aqua terminal
Inside Aqua
Request PBS Pro scheduler Compute nodeShared CPU and memory CPU coresSystem RAM Your shell runson the compute node 1 CPU core · 1 GB RAM · up to 5 min Runtime begins at allocation5 min limit Waiting for PBS to assign resources.A job ID tracks the request. It is not a start signal. Session ended. Allocation released.The resources are available for other jobs.
P12 / 46

Interactive or batch: when would you use each?

02 / UNDERSTAND THE WORK

Interactive or batch?
When would you use each?

Interactive

“Why are values missing in my data?”

Inspect the data, try a command,
then decide what to do next.

Batch

“Let preprocessing run while I write.”

Lily submits her prepared script.
It runs and saves results without further input.

Choose a live investigation or prepared unattended work On the left, inspect a missing value and decide the next command. On the right, the prepared preprocessing script reads inputs, processes data and saves results. Both cases are visible immediately. Both examples replay automatically: the researcher inspects a response and chooses another command, while the prepared script proceeds to saved results. You > _ Your terminal Try a step Inspect Live compute session Data sample row 112 row 2missing row 38 One value needs investigation Explore · test · decide Saved script Resources + time Read inputs Preprocess Save results Compute node Runs the script Reading inputs Run Save Results + log No further user input

You inspect the data and choose the next step.

Lily can keep writing while the script runs.

Both interactive and batch jobs can use CPUs or GPUs.

P13 / 46
02 / UNDERSTAND THE WORK

The same task.
Now submit it as a batch job.

A PBS file is a plain-text shell script containing a resource request and the commands to run.

hello.pbsSave the instructions in one file
#!/bin/bash
#PBS -N hello
#PBS -P YOUR_RPID
#PBS -l select=1:ncpus=1:mem=1GB
#PBS -l walltime=00:05:00
#PBS -j oe
#PBS -m abe

cd "$PBS_O_WORKDIR"
hostname
echo "hello from my job"
Submit on the login nodeqsub hello.pbs

PBS reads the request

Lines beginning with #PBS

-N / -P
Job name / Research Project ID (RPID).
Find your RPID in the Data Management Plan ↗
-l
1 CPU core · 1 GB RAM · up to 5 min.
-j oe
Combine output and errors in one log.
-m abe
Email on abort, begin and end.

The shell runs the same commands

On the compute node, once resources are allocated

cd selects the submission directory.

Example outputhello.o<job-number>
cpu1n023
hello from my job
P14 / 46

One research task: classify unseen movie reviews

03 / FROM TASK TO RESULT

One research task
Classify unseen movie reviews

THE TASK

Learn from reviews.
Generalise to new ones.

Fine-tune DistilBERT, a pretrained text model, using reviews labelled positive or negative.

The IMDb benchmark25,000 training reviews
25,000 separate test reviews

One review. One prediction.

EXAMPLE REVIEW01 / 04
Two hours of my life I will never get back. The plot made no sense and the acting was wooden.
REFERENCE LABELNegative
Label held back during prediction
FINE-TUNED MODELDistilBERTText classifier
EXAMPLE PREDICTIONNegative
Matches the
reference label

Try one epoch, estimate the time,
then run the full task in batch.

P15 / 46

From our research task to an Aqua job

03 / FROM TASK TO RESULT

From a Python program
To a complete run on Aqua

PREPARE ONCEKEEP THE OUTPUTS Your project on Aqua imdb_sentiment.pyLoad inputs · train · evaluateSave the model and results Python + librariesThe project environment Cached inputsIMDb + pretrained DistilBERT PBS allocates compute ALLOCATED COMPUTE imdb_sentiment.py 01Load software + inputs 02Train + evaluate 03Save outputs ModelInteractive trial → batch run model/Classify new reviews results.jsonEvaluation + runtimeRecorded run settings Job log: progress + errors Load the same program, environment and inputs on allocated compute.
P16 / 46

Prepare the software and inputs before submission

03 / FROM TASK TO RESULT

Prepare the project
Before running the first epoch

THE PYTHON ENVIRONMENT

The software our program uses

A Python interpreter and the installed libraries that the program imports.

Project environment · .venv/
Python
PyTorchGPU computation
TransformersThe text model

Plus the libraries for data and evaluation

The trial and batch job use this environment.

PREPARE THE PROJECT
01

Set up Python on the login node

Record the libraries, including GPU-enabled PyTorch,
in the project’s dependency files.

pyproject.tomlRequired packages
uv.lockResolved versions
uv syncInstall the environment
02

Download the model and reviews

Fetch the pretrained model and reviews without training.

uv run python imdb_sentiment.py --fetch-only

uv run selects this environment; training reads inputs offline.

P17 / 46

Try one epoch: check the pipeline and measure time

03 / FROM TASK TO RESULT

Try one epoch interactively
Check the pipeline. Measure the time.

REQUEST A GPU SESSION · FROM THE LOGIN NODE
qsub -I -P YOUR_RPID -m abe \
  -l select=1:ncpus=6:ngpus=1:mem=32GB:gpu_id=H100 \
  -l walltime=02:00:00

One H100 MIG slice (~10 GB GPU memory). Exit when finished.

ON ALLOCATED COMPUTE · IN THE PREPARED PROJECT
mkdir -p runs/trial
uv run python imdb_sentiment.py \
  --epochs 1 --batch 16 --seed 42 --lr 2e-5 \
  --model-dir runs/trial/model \
  --out runs/trial/results.json

Same full dataset and settings as the batch job.
Only the epoch count changes; trial outputs stay separate.

Follow the whole execution path

The prepared projectPython environment + cached inputs
Compute node · 4 physical H100s One H100 H100H100H100 Your slice · 1g.10gb (~10 GB)
runs/trial/model/   +   results.json

Check CUDA, the completed epoch and saved files.
Record elapsed time and the GPU slice used.

P18 / 46

The research job script: request and execution

03 / FROM TASK TO RESULT

One file for the batch job
Resources first. Then the program.

workshop.pbs
#!/bin/bash
#PBS -N imdb_demo
#PBS -P YOUR_RPID
#PBS -l select=1:ncpus=16:ngpus=1:mem=64GB:gpu_id=H100
#PBS -l walltime=01:00:00
#PBS -j oe
#PBS -m abe

cd "$PBS_O_WORKDIR"
mkdir -p "runs/demo"
uv run python imdb_sentiment.py \
  --epochs 3 --batch 16 --seed 42 --lr 2e-5 \
  --model-dir "runs/demo/model" \
  --out "runs/demo/results.json"
PBS READS THE REQUEST

Our starting allocation

16 CPUs · 64 GB RAM · 1 H100
1 hour as a conservative starting limit.
Refine after the full-H100 run.

THE SHELL RUNS THE COMMANDS

Use the prepared environment

cd enters the submission directory.
uv run uses the project’s .venv.
No separate activation is needed.

Run and keep the outputs

Save the model and results in
runs/demo/.

P19 / 46

Submit the work and follow its job ID

03 / FROM TASK TO RESULT

Submit the prepared work
Follow the job, not just the submission.

AQUA TERMINAL
PowerShell · Your computerworkshop.pbs
PS C:\Users\user> ssh aqua
[user@aquarius01 ~]$ cd ~/hello-aqua
[user@aquarius01 hello-aqua]$ qsub workshop.pbs
12345678.aqua
[user@aquarius01 hello-aqua]$ qstat -u $USER
aqua: Req'd Req'd Elap Job ID Username Queue Jobname SessID NDS TSK Memory Time S Time ------------------------------------------------------------------------------------ 12345678.aqua user gpu_bat* imdb_demo -- 1 16 64gb 01:00 Q --
[user@aquarius01 hello-aqua]$ qstat -T
aqua: Est Req'd Req'd Start Job ID Username Queue Jobname SessID NDS TSK Memory Time S Time ------------------------------------------------------------------------------------ 12345678.aqua user gpu_bat* imdb_demo -- 1 16 64gb 01:00 Q 16:14
[user@aquarius01 hello-aqua]$ qstat -f 12345678.aqua
Job Id: 12345678.aqua Job_Name = imdb_demo job_state = Q queue = gpu_batch_exec ... Resource_List.walltime = 01:00:00 ... comment = Not Running: Insufficient amount of resource: ngpus (R: 1 A: 0 T: 100) ... estimated.start_time = Mon Sep 21 16:14:04 2026
Connect to Aqua
READ THE JOB’S STATUS

Has my job started?

Q means queued. PBS accepted the job, but execution has not started.

When might it start?

16:14 is the current estimate. It can change as the schedule changes.

What is blocking it?

The scheduler’s comment reports insufficient available GPUs for this request.

P20 / 46
03 / FROM TASK TO RESULT

The completion email arrives.
Now read the saved results.

OUR BATCH RUN

Project directory

01
runs/demo/results.json

Counts, settings, accuracy
and resource observations

02
runs/demo/model/

Saved model and tokenizer
for classifying new reviews

imdb_demo.o<job-number>

Progress, errors and PBS summary

less imdb_demo.o12345678
cat runs/demo/results.json
PBS completion email#PBS -m abe
PBS JOB 12345678.aqua · Exit_status=0
imdb_demo.o12345678Recorded run · ID anonymised
... {'epoch': 3, ...}
accuracy  0.9161 on 25,000 test reviews
done ... in 480.0s -> runs/demo/results.json
Execution trailProgram: 8 min.
Check errors and
the save message.
PBS Job 12345678.aqua
Wall time : 00:08:37
Mem usage : 1272032kb
PBS summaryWhole-job runtime
and memory use.
runs/demo/results.jsonSaved result
{
  "job_id": "12345678.aqua",
  "train_reviews": 25000, "test_reviews": 25000,
  "epochs": 3, "device": "cuda",
  "gpu": "NVIDIA H100 80GB HBM3",
  "accuracy": 0.9161
}
Intended task?Match ID, counts,
epochs and GPU.
Model result91.61% of test reviews
classified correctly.
P21 / 46

Why suitable resource requests matter

03 / FROM TASK TO RESULT

Why not request extra, just in case?
PBS has to find room for it.

01 · A LIMIT

Enough to finish

Too little memory or walltime can stop the job.

Leave room above the observed need.

02 · A BOOKING

Capacity held for this job

Allocated CPUs, RAM and GPUs are unavailable to other jobs while yours runs.

Keep the headroom that helps the GPU work.

03 · A FIT TO FIND

Resources together, in time

PBS must find the requested hardware for the requested duration.

Extra size or time can rule out an opening.

SO HOW DOES PBS CHOOSE WHAT STARTS?
1

Priority: which job is considered first?

Requested size, fair share and eligible waiting affect the score. Smaller does not automatically rank higher.

2

Fit: which job can start now?

Hardware and walltime must fit the available opening. A shorter request may fit before reserved work.

P23 / 46
03 / FROM TASK TO RESULT

What changes the priority score?
One request. Two views of the same score.

P24 / 46

Backfilling uses a gap without delaying a reservation

03 / FROM TASK TO RESULT

How does a lower-ranked job start first?
Watch the queue and the GPU schedule.

P25 / 46

One submission, ten experiments, with controlled concurrency

03 / FROM TASK TO RESULT

One submission. Ten experiments.
Control how many run at once.

P26 / 46

What changes for the researcher?

04 / FROM JOB TO RESEARCH

What changes for the researcher?
HPC closes a specific research gap.

“Submit a job array
to run independent
configurations
in parallel.”
Sam
Sam
“Set mem in PBS
to reserve RAM for
my analysis on
one compute node.”
Alex
Alex
“Use a multi-node
job
for processes
that communicate
between machines.”
Priya
Priya
“Submit a
batch script that
keeps running
after I log out.”
Lily
Lily
“Use shared project
storage
so every job
reads the same
input files.”
Maya
Maya
P27 / 46

Where could HPC help your research?

04 / FROM JOB TO RESEARCH

Where could HPC help
your research?

For the task you had in mind:

01

What gap needs addressing?

What does your research require that your current setup cannot support?

02

Which HPC approach could help?

Job arrays, a larger-memory allocation, communicating processes across nodes,
unattended batch execution or shared storage.

03

What would you need help with to make your first attempt?

Identify one step you would need help understanding or carrying out.

Reminder: Choose HPC for the gaps it can address in your research,
not simply for the power it offers.

P28 / 46

Stay calm, and take a break

PART 1 → PART 2

Stay calm,
and take a break.

FIVE-MINUTE BREAK
05:00
UP NEXT · PART 2

Working with an AI agent on Aqua.

P29 / 46

Working with HPC: investigate what comes back

05 / FROM ADVICE TO ASSISTANCE · TRADITIONAL WORKFLOW

Working with HPC
What comes back shapes what you do next.

An HPC attempt becomes an investigation The researcher prepares a project and tries it on Aqua. The job stops because the launched Python environment lacks a required package. Comparing the prepared project with the job log exposes the mismatch. Documentation and discussion help the researcher revise which environment is used, try again, and inspect fresh evidence. Passing the environment check does not establish the research outcome. The complete workflow remains visible throughout. Documentation & examples HPC docs · software docs · working code Read · compare · learn People & support Colleagues · supervisors · eResearchAsk · discuss · clarify YOUR RESEARCH TASKRun the analysis. PREPARE / EDITYour projectCode, data, environment and job script Code + data EnvironmentPyTorch Job script THE ANALYSIS NEEDSThe project's Python environment JOB SCRIPT LAUNCHESSystem Python Will this runas intended? You investigate and decide. Research outcome: interpret and check findings. REQUEST / RUN / MONITORAquaTerminal / SSH · interactive or batch Login nodePBS schedulerAllocated compute RETURNED EVIDENCE / JOB LOG Ready to try Inspect what the job reports.Then decide the next step. Logs · saved results · resource usage Edit Try Inspect
P30 / 46

Working with an LLM: advice becomes action through you

05 / FROM ADVICE TO ASSISTANCE · LLM-ASSISTED WORKFLOW

Working with an LLM
Advice becomes action through you.

The researcher connects LLM advice to the actual HPC work The same research task, project and Aqua execution as the traditional workflow. The researcher chooses code and error context to share with an LLM, assesses its explanation, edits the project, runs a check on Aqua and brings fresh evidence back to the conversation. Documentation and people remain sources of help. In this chat-based arrangement the LLM does not directly access the project or execute commands. Documentation & examples HPC docs · software docs · working code Read · verify · share with the LLM People & support Colleagues · supervisors · eResearchAsk · discuss · clarify YOUR RESEARCH TASKRun the analysis. ASK / DISCUSS / CLARIFY LLM conversation Explain · draft · diagnose YOU SHARE “Why does this job stop at startup?” Job: system Python · project: .venv LLM HELPS YOU REASON Explain unfamiliar commands. Help interpret code and errors. Ask why. Check the explanation. Chat uses the context you provide. PREPARE / EDITYour project Code + data EnvironmentPyTorch Job script The project's Python environment Launch: system Python REQUEST / RUN / MONITORAqua Login nodePBS schedulerAllocated compute RETURNED EVIDENCE / JOB LOG No module named 'torch' What does thiserror mean? You investigate and decide. Select &share Read &question Apply edit Run / retry Inspect Research outcome: interpret and check findings.
P31 / 46

Working with an agent: discuss, act and inspect the evidence

05 / FROM ADVICE TO ASSISTANCE · AGENT-ASSISTED WORKFLOW

Working with an agent
Discuss the work. Act on it. Check what comes back.

You and an agent collaborate in the same working environment You and the agent discuss objectives, findings, changes and approvals directly. Both read documentation independently. People and support connect to you. You access the shared project and Aqua directly; the agent uses tools and configured SSH access under your account for approved actions. Project work is submitted to Aqua and status, errors, logs and results return for inspection. Conversation and returned tool observations provide context for the LLM. Persistent notes or memory, where configured, live in writable records that can be read and updated. File tools read and edit the project and its documentation, terminal tools execute permitted commands on Aqua, and returned evidence reaches the agent to inform its next action and discussion with the researcher. The illustration follows an environment mismatch, an agreed edit and a permitted import check, not a completed research result. People & support Colleagues · supervisors · eResearch Ask · discuss Documentation & examples HPC docs · software docs · working examples Read Read YOUR RESEARCH TASK Run the analysis. You investigateand decide. Agent Memory Context · saved notes LLM Understand the task Tool call Observation Tools Files · sources Terminal / SSH You ask: investigate the startup error. Explain the cause before editing. Goals · questions · approvals Findings · proposals · progress Direct access · editor · shell · SSH SHARED WORKING ENVIRONMENT Agent tools use your account and granted permissions. PREPARE / EDITYour project Code + data EnvironmentPyTorch Job script The project's Python environment python imdb_sentiment.py Notes / memory · setup, decisions, checks REQUEST / RUN / MONITORAqua Login nodePBS schedulerAllocated compute RETURNED EVIDENCE / JOB LOG No module named 'torch' Submit / run Status · logsresults · errors Run / monitor Read / edit project files Tool output
P32 / 46

How an agent decides what to do next

05 / FROM ADVICE TO ASSISTANCE · INSIDE THE AGENT

How an agent decides what to do next
The result becomes part of the next decision.

Inside the agent: context, LLM, tools, memory and feedback Your task and instructions, retrieved material, and selected memory form the current context supplied to the LLM. The LLM can request a tool action or respond to you. The agent runtime checks available access and permissions before executing an action. Tools inspect or change the real project and Aqua environment. Returned evidence updates the context for the next model decision. Tools can save notes and retrieve them later. This illustrative import-error investigation pauses for approval before editing and ends by reporting the limits of the check. REQUEST Investigate the failed import. Explain the cause before editing. RESPONSE / QUESTION Inspecting the project… An answer needs evidence. AgentRuntime: context · execution · permissions Current context Task · instructions · tool definitions The job cannot import torch. The cause is still unknown. Context LLM Choose what to inspect first Decide · request · respond Tool call Tools Read matching log and launch command Files · terminal · sources Execute Project & Aqua EnvironmentPyTorch Job script The actual project files Your account · granted access AQUA · TERMINAL / SSH No module named 'torch' Existing job log Permission checks before execution Result Tool result RETURNED EVIDENCE Read the files to establish the cause. A guess is not a tool result. Update context Saved memory Notes · retained findings Where configured; retrieve as needed. Retrieve Tools can write notes for later use. Start with the evidence: which Python actually ran? The LLM can request another tool action, ask you, or return an answer.
P33 / 46
05 / FROM ADVICE TO ASSISTANCE · WHY IT HELPS

What becomes easier with an agent?
Less carrying context. More connected work.

Less manual copying

Scriptlaunch.shJob logstderrRead Agent · file tools launch.shpython train.py stderrNo module named 'torch' Contents from the actual project

Inspect accessible scripts and logs directly.

Connected troubleshooting

Launch commandpython train.pyProject env: PyTorchCompare with the job errorAgreed editthen check Aqua · allocated sessionJob error: no torchCheck not run yetInspect → edit → check

Compare the evidence, make an agreed edit, check it.

Help with repetitive preparation

JobtemplateAgreed scopePrepare configurations + output locationsRun Aconfig Aout/A/Run Bconfig Bout/B/Run Cconfig Cout/C/

Prepare scripts, configurations and outputs within scope.

Learning while doing

PBS job endedExit_status = -29walltime 7226exceeded limit 7200 “Why did my job stop?” PBS enforced walltime.2 h 26 s used; 2 h requested.Review walltime before retrying.

Learn why a job stopped and what to check next.

Less operational work to carry. More room to understand and direct it.

P34 / 46

When the agent can act, what becomes your role?

05 / FROM ADVICE TO ASSISTANCE

When the agent can act,
what becomes your role?

Research supervision and researcher-agent collaboration Two parallel exchanges. A supervisor discusses the question, direction and expectations with a PhD student, who returns findings, questions and proposed next steps. A researcher discusses the objective, context and boundaries with an agent, which returns findings, questions and proposed next steps. Each relationship has separate labelled arrows in both directions. The analogy concerns organising and reviewing work, not equivalent understanding or accountability. A FAMILIAR RESEARCH RELATIONSHIP Supervisor Discuss the question Direction & expectations Findings & questions Proposed next steps PhD student Investigate · try · evaluate WORKING WITH AN AGENT Researcher Objective & context Agree the boundaries Findings & questions Proposed next steps Agent Inspect · act · check

Agree the work. Give room to act. Review the evidence.

An analogy for direction and review. People and agents differ in understanding and accountability.

P35 / 46
05 / FROM ADVICE TO ASSISTANCE

Products keep changing.
Learn how to make them work with your HPC workflow.

LLM FAMILIES

GPT
Claude
Gemini
DeepSeek
Qwen
Llama
Mistral
Grok
Gemma
Kimi
GLM
Command
Jamba
Nova
MiniMax
Hunyuan
ERNIE
Yi
InternLM
Baichuan
OLMo
Falcon
Nemotron
Granite
Solar
Liquid
Reka
Cogito
MiMo
LongCat
Step

AI APPS & INTERFACES

ChatGPT
Claude app
Gemini app
Perplexity
Poe
NotebookLM
Meta AI
Doubao
Yuanbao
Kimi app
Kagi Assistant
Pi
LM Studio
Ollama
Open WebUI
Cherry Studio
LobeHub
Monica
YouMind

AGENT PRODUCTS & PLATFORMS

Codex
Claude Code
Cursor
Gemini CLI
GitHub Copilot
Cline
Devin
Kilo
Kiro
Junie
OpenCode
goose
OpenHands
Antigravity
Replit Agent
Lovable
v0
TRAE
Qoder
Zencoder
Manus
Skywork
Flowith
Dify
Coze
n8n
Zapier Agents
CrewAI
Hermes Agent
OpenClaw

The products change. The working principles transfer.

Learn to integrate an agent into your research pipeline and HPC: connect it, direct its work, and check the results.
Examples, not an exhaustive list. Roles can overlap.   Logos: LobeHub Icons · icons.lobehub.com
P36 / 46
06 / CONNECT AN AGENT TO AQUA

Connect your agent to Aqua.
Four things to configure before you begin.

01 Local agent application

Install your chosen application on your computer.
Open the local folder for your research project.

Keep the agent application off Aqua’s login nodes.

CHECKAsk it to inspect and explain a local project file.

02 Model connection

Sign in, or configure a supported provider and API key
in the application’s settings. Choose a capable model.

An affordable coding model is a useful starting point.

CHECKTry a small coding question and review the answer.

03 SSH access and permissions

Keep the private key local; register the public key on Aqua.
Test SSH yourself, then allow the agent to use it.

Start with manual approval of remote commands.

CHECKTest the SSH login:
ssh <user>@aqua.qut.edu.au

04 Aqua and project guidance

Ask the agent to read Walltime Chronicles’ agent index.
Attach relevant Aqua docs and provide project paths,
the environment and a working PBS script.

State permitted actions and where outputs should go.

CHECKAsk it to identify the setup before proposing changes.
P37 / 46
06 / CONNECT AN AGENT TO AQUA

Give the agent a starting point.
Turn Aqua guidance into reusable project knowledge.

Claude CodeRecorded local run · excerpts

Read https://zhipenghe.me/Walltime-Chronicles/llms.txt and its Aqua guide, then save the working rules and source links to docs/aqua-guide.md in this project for future Aqua tasks.

I'll fetch the llms.txt entry point first to find the Aqua guide links.

WebFetch(https://zhipenghe.me/Walltime-Chronicles/llms.txt)
# Walltime Chronicles Content Summary
## Full Index of Links and Descriptions
…
WebFetch(https://zhipenghe.me/Walltime-Chronicles/agents/aqua-guide.txt)
Read(<project>)
EISDIR: illegal operation on a directory, read '<project>'
I appreciate your request, but I need to clarify
what you’re asking me to do.
…
returning the entire document word-for-word would violate
the constraint you’ve also specified …
WebFetch(https://zhipenghe.me/Walltime-Chronicles/agents/aqua-guide.txt)
WebFetch(https://zhipenghe.me/Walltime-Chronicles/cheatsheet/)
# Aqua HPC Cheatsheet - Structured Reference
## PBS/QSUB Commands
…
# Structured Extraction: QUT Aqua Guidance
## (1) System Overview Facts
…

Fetched both. Writing the distilled rules and links to the project's docs.

Write(<project>\docs\aqua-guide.md)
File created successfully at:
<project>\docs\aqua-guide.md

Saved to `docs/aqua-guide.md`. It covers: - **System model** — PBS, login vs compute nodes, queue time isn't failure, filesystem and environment caveats. …

Working…
01 / READ

Follow the source.

Read the index, then the Aqua guide.

02 / RECOVER

Adjust when tools fail.

After a failed read and limited web response, fetch a summary and cheatsheet.

03 / SAVE & REVIEW

Keep reusable guidance.

Saved docs/aqua-guide.md with rules and source links. Review before reuse.

Read the actual saved guide · Inspect the transcript

P38 / 46
06 / WORKING WITH AN AGENT ON AQUA

The same IMDb experiment.
Now work through it with an agent.

Same code. Same Aqua workflow. Agent assistance at each step.

1

Investigate

Read the project.

2

Review & submit

Approve the action.

3

Interpret

Check the evidence.

Less manual handoff. You stay in control.

P39 / 46
06 / WORKING WITH AN AGENT ON AQUA

1. Start with a task it can investigate.
Read the project before proposing the work.

Claude CodeLocal session · illustrated replay

Inspect hello-aqua and prepare the three-epoch IMDb run. Explain the setup. Ask before submission.

I’ll read the entry point, environment and PBS script before proposing an execution command.

Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "cd ~/hello-aqua && sed -n '1,230p' pyproject.toml")
[project]
name = "hello-aqua"
Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "cd ~/hello-aqua && sed -n '1,230p' imdb_sentiment.py")
MODEL = "distilbert/distilbert-base-uncased"
DATASET = "stanfordnlp/imdb"

The source defaults to two epochs. Your request is for three. I’ll check whether the workshop PBS script overrides that and keeps the model and summary outputs separate.

Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "cd ~/hello-aqua && sed -n '1,230p' workshop.pbs")
uv run python imdb_sentiment.py \
  --epochs 3 --batch 16 --seed 42 --lr 2e-5 \
  --model-dir "runs/demo/model" \
  --out "runs/demo/results.json"

workshop.pbs changes to PBS_O_WORKDIR and launches the script with uv run: three epochs, batch 16, seed 42, lr 2e-5. It saves the model in runs/demo/model and the summary in runs/demo/results.json. Next: review the resource request.

Working…esc to interrupt
? for shortcuts
Your computer

Set the task and boundary.

Name the project and run. Ask before submission.

Aqua login environment

Read the remote files.

SSH returns file contents that may enter model context.

Application + model

Check the actual command.

The code defaults to two epochs; this job requests three.

Aqua login environment

Identify the outputs.

Check the environment, settings, model path and result path.

P40 / 46
06 / WORKING WITH AN AGENT ON AQUA

2. Review the job before it runs.
Approve the action. Follow the job.

Claude CodeLocal session · illustrated replay

Review the job and output destinations. Show me the exact submission before you run it.

The workshop script requests 16 CPUs, 64 GB and one H100 for up to one hour, with joined logs and begin/abort/end mail. The model goes to runs/demo/model; the summary goes to runs/demo/results.json. Check for existing outputs before reusing these destinations for a new run.

Bash(ssh aqua "cd ~/hello-aqua && cat workshop.pbs")
#PBS -l select=1:ncpus=16:ngpus=1:mem=64GB:gpu_id=H100
#PBS -l walltime=01:00:00
#PBS -j oe
#PBS -m abe
cd "$PBS_O_WORKDIR"

Ready to submit one job from ~/hello-aqua. Requesting approval for qsub workshop.pbs.

Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "cd ~/hello-aqua && qsub workshop.pbs")
12345678.aqua
Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "qstat 12345678")
12345678.aqua    imdb_demo    Q  (queued)
Bash(ssh aqua "qstat 12345678")
12345678.aqua    imdb_demo    R  (running)

The batch job runs independently of this conversation. I can retrieve its status and saved output later.

Working…esc to interrupt
? for shortcuts
Aqua login environment

Review the job.

Check settings, resources and output paths.

Your computer
Approval required

Approve this command once.

Review the full SSH command before submission.

Aqua login environment

Keep the PBS job ID.

Submission joins the queue; it does not start compute.

Allocated compute

The job runs independently.

It saves outputs on Aqua, even after the conversation ends.

P41 / 46
06 / WORKING WITH AN AGENT ON AQUA

3. Interpret the result, not just the exit code.
Ask what the evidence actually establishes.

Claude CodeLocal session · illustrated replay

Read the completed run’s log and results. Tell me what succeeded and what still needs judgement.

Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "cd ~/hello-aqua && cat runs/demo/results.json")
"train_reviews": 25000, "test_reviews": 25000,
"epochs": 3, "device": "cuda",
"gpu": "NVIDIA H100 80GB HBM3",
"accuracy": 0.9161, "elapsed_s": 480.0
Bash(ssh -o BatchMode=yes -o ConnectTimeout=15 aqua "cd ~/hello-aqua && tail -n 90 imdb_demo.o12345678")
accuracy  0.9161 on 25,000 test reviews
done      accuracy 0.9161  in 480.0s  -> runs/demo/results.json, model in runs/demo/model/
Wall time        : 00:08:37
Exit_status      : 0

The matching log and results.json show three epochs on 25,000 training reviews and evaluation on 25,000 test reviews. Final accuracy: 91.61%. The log records saved outputs and predictions for two example reviews.

The epoch-three evaluation reports 93.22%, but the final evaluation and results.json both report 91.61%. These are different observations; I’ll report the final result. The source enables load_best_model_at_end. I have not investigated checkpoint selection further.

Why does the program say 8 minutes, but PBS says 8:37?

The clocks cover different parts of execution. PBS reports the whole job; the program times its own work. These records do not break down the extra 37 seconds.

These files establish what the recorded run produced. I have not rerun training or independently loaded the model. Whether the method is adequate remains a research judgement.

Working…esc to interrupt
? for shortcuts
Aqua login environment

Match the job and evidence.

Read the result and matching log, so evidence from different runs is not mixed.

Aqua login environment

91.61% final accuracy

Evaluated on 25,000 test reviews after three epochs.

Aqua login environment

8 min 37 s walltime

Exit status 0. Program timing: 8 min.

Application + model

93.22% is an epoch score.

Report the final saved evaluation: 91.61%.

Application + model

Know what remains uncertain.

Explain what is known and what still needs checking.

P42 / 46
07 / DIRECTING THE WORK

Set the scope. Control the actions.
Check the work that comes back.

01

Define the scope.

State the outcome, what must stay the same
and where the agent should stop.

“Keep the experiment settings.
Prepare the job. Ask before submission.”
02

Control the actions.

Configure supported tool permissions.
Begin with approval for remote changes and jobs.

Read the project → permitted
Submit a job → approve the exact action
03

Check and redirect.

Review consequential changes and returned evidence.
Interrupt repeated edits without a diagnosis.

“Stop editing. Show the error, your changes
and what is still uncertain.”
Instructions say what it should do. Permissions limit what it can do.
Review establishes what it actually did.
P43 / 46
08 / YOUR NEXT STEP

Choose one useful task from your research.
Give it context, boundaries and a finish line.

YOUR FIRST TASK
Help me [achieve an outcome],
using [project files and guidance].

You may [take these actions].
Finish by showing [result + evidence].

Explain a PBS script · investigate a failed job
Prepare a change for review

KEEP REUSABLE GUIDANCE WITH THE PROJECT

Give the next interaction
a useful starting point.

LocateProject paths, environment,
Aqua guidance and a working PBS script.
PreserveResearch settings and existing outputs.
BoundPermitted actions and when to ask.

Use the instruction-file format your agent supports.

P44 / 46
08 / YOUR NEXT STEP

What is one task
you would now
approach differently?

Research workspace with AI assistance and shared HPC resources An illustrative cycle: AI assistance helps prepare a job in the researcher’s project; the job travels to HPC resources; results return for inspection with AI assistance. The researcher directs the task. This is a conceptual overview, not a recorded execution. HPC resources Run experiments · analyse data Your research project code / data / job script AI agent assistance Read code · prepare the job Read logs · explain the results HPC expands what you can run. AI agents help you put it to work.

You decide what is worth doing
and what the results mean.

P45 / 46

Resources & acknowledgements

08 / TAKE IT INTO YOUR RESEARCH

Resources & acknowledgements
Keep the guidance. Continue the work.

Acknowledge QUT and eResearch

Remember to include in your paper:

“We acknowledge support from the Queensland University of Technology (QUT) through its provision of subsidised access to specialised research infrastructure including HPC and the eResearch team at QUT for providing expertise in enablement of this project.”

AI assistance

OpenAIOpenAI GPT-6 AstraClaudeClaude Fable 5.1 & Opus 5

Workshop materials developed with assistance from these models. Content reviewed and final decisions made by the presenter.

Questions & discussion
P46 / 46

Inside a compute node: processors, memory and files

APPENDIX / INSIDE A COMPUTE NODE

Inside a compute node:
where your program and data go

How a program uses processors, working memory and stored files Shared storage keeps input and output files. The program reads inputs into system RAM. CPU cores run the program and read and write RAM. When GPU-aware software is used, the CPU dispatches supported operations to a GPU; working data transfers between system RAM and GPU memory. The GPU computes using its memory. Results must be written to storage to keep them after the run. This is an illustrative discrete-GPU node, not a physical wiring diagram. ONE COMPUTE NODE Illustrative node with a discrete GPU · data paths, not physical wiring Storage Keeps your files Inputs + saved results Shared filesystem Read Save CPU Runs your program CPU cores execute instructions Read / write System RAM Active data + intermediate results GPU (when used) Runs supported parallel operations GPU-aware software dispatches work GPU memory VRAM Working data for GPU operations Transfer working data

Processors do the work. Memory is the workspace; storage keeps the files.

A01 / 08

Aqua hardware at a glance

APPENDIX / AQUA HARDWARE

Aqua hardware
At a glance

CPU nodes

CPU analysis
and simulations

Request only the CPU cores your program can use.

Aqua CPU node
192 physical cores · 1.5 TB RAM

GPU nodes

GPU

Software that
uses a GPU

Check GPU support and the GPU memory your workload needs.

Aqua GPU memory per full card
H100: 80 GB · A100: 40 GB

Large-memory node

More RAM on
one machine

Use this when your workload needs more RAM than a standard node provides.

Aqua large-memory node
6 TB RAM · 192 physical cores

Request what the job needs.The node’s full capacity is shared; your allocation may use only part of it.

Installed capacities shown. Usable resources are lower; interactive limits differ. GPU memory is separate from system RAM.

A02 / 08

Finding your Research Project ID in DMP

APPENDIX / PROJECT IDENTIFIERS

Your Research Project ID
Find it in your Data Management Plan.

An RPID identifies the research project in QUT’s Data Management Planner (DMP).

  1. Open the Data Management Planner

    Sign in at data-mgmt-plan.qut.edu.au.

  2. Use your project’s plan

    Existing project: ask the plan lead to add you as a collaborator.
    New project: Start Data Management Plan → fill in details → Save.

  3. Find its RPID and use it for this project

    Use a project ID you have access to.
    Replace YOUR_RPID in the submission.

Project ID ≠ job ID. DMP identifies the project. PBS assigns a new job ID for each submission.

#PBS -P YOUR_RPID

In a batch job’s PBS header.

Or supply it when submitting:

qsub -P YOUR_RPID job.pbs

Uppercase -P · use the RPID for this research.

← Back to the PBS file

A03 / 08

A small interactive session on Aqua

APPENDIX / INTERACTIVE COMMANDS

A small interactive session
The commands run on a compute node

qsub -I -P YOUR_RPID \
  -l select=1:ncpus=1:mem=1GB \
  -l walltime=00:05:00

A request for a live shell

-I means interactive.
One CPU core, 1 GB RAM,
up to five minutes after the job starts.

PBS may queue the request. When it starts, you receive a shell on a compute node.
hostname
echo "hello from my job"
exit

Observe, then leave

hostname shows where commands run.
echo prints a message in the session.
exit releases this allocation.

← Back to the allocation demonstration
Already logged in to Aqua. Replace YOUR_RPID with your project ID. This request is for the tiny example shown.

A04 / 08

Several independent experiments are not one communicating experiment

APPENDIX / EXECUTION ARRANGEMENTS

Independent experiments are not
one communicating experiment.

Sam: complete experiments

Run A
train + evaluate
result-a.json
Run B
train + evaluate
result-b.json
Run C
train + evaluate
result-c.json

Each process produces its own research result.
No communication between runs is required.

Priya: one communicating experiment

Machine AOwn CPU and RAM
Coordinator
Waits for a response
request →← response
Machine BOwn CPU and RAM
Worker
Processes the request
One experiment’s record: communication and outcome

The software launches and coordinates these components.

A cluster network may differ from the intended deployment.
A05 / 08
APPENDIX / ARRAY JOBS

The index selects the work
Keep the working script. Change the inputs.

sweep.pbs · array-specific lines
#PBS -J 1-10%3
#PBS -m a

cd "$PBS_O_WORKDIR"
read -r lr seed < <(
  sed -n "${PBS_ARRAY_INDEX}p" configs.tsv
)
run="runs/sweep/$PBS_ARRAY_INDEX"
mkdir -p "$run"
uv run python imdb_sentiment.py \
  --epochs 3 --batch 16 --lr "$lr" --seed "$seed" \
  --model-dir "$run/model" \
  --out "$run/results.json"
Reuse the checked request

Keep the resource directives from the revised job. Each member receives that allocation.

Index → row → arguments

configs.tsv has ten rows, no header:
learning rate, then seed.

Keep results separate

The index names the output directory.
Abort-only mail avoids a message for every start and finish.

A06 / 08
APPENDIX / ARRAY JOBS

An array finishes as a collection
Bring every result back to its settings

THREE SOURCES · ONE MEMBER INDEX
configs.tsvLearning rate and seed for each row
PBS member logsExit status and whole-job runtime
runs/sweep/<index>/results.json and the saved model
JOIN BY ARRAY INDEX

One comparison table

Index + settingsExit statusValidation scoreRuntime

Account for every planned member.
Missing or failed runs stay visible.

Inspect failed logs before retrying.
Compare completed runs under the same protocol.

Select on validationMake a fixed split from the training data.
Evaluate once on testUse the untouched test set for the selected model.

Sam’s campaign: a checked program, a justified request, and identifiable results for every configuration.

A07 / 08

Estimate batch walltime from the one-epoch trial

APPENDIX / WALLTIME ESTIMATE

How long should we request?
Build the estimate from the trial

The same data and settings, from one epoch to three.

Interactive trialObserve one epoch
SStartup
ETrain + evaluate
+ checkpoint
FFinish
Batch estimateAllow for three epochs
SOnce
EEpoch 1
EEpoch 2
EEpoch 3
FOnce
+ AAllowance
S + 3 × E + F + ARepeat the epoch work; count startup and finish once.
FIRST BATCH REQUEST#PBS -l walltime=HH:MM:SS

Queue waiting is separate. Keep an allowance; do not subtract an assumed full-GPU speedup.

A08 / 08